Regulatory Updates as Content Triggers for Developer Products
Regulatory changes are content briefs with built-in deadlines and audiences.
Regulatory bodies now produce output continuously rather than as a single document that a legal team files away once a year. It arrives constantly, in overlapping waves, from different bodies, on different schedules, and a developer product's documentation is almost always behind what compliance now actually requires. Most teams still treat a regulatory update the way they'd treat a tax form: something that shows up, gets handled by legal, and disappears into a drawer. That model made sense when regulation moved slowly. It moves far faster than that model assumes.
Regulatory updates as a live content signal
The EU AI Act shows what this cadence looks like in practice. Prohibited AI practices were banned starting February 2025. General-purpose AI rules took effect in August 2025. High-risk AI system obligations under Annex III arrive in August 2026, and some of those obligations have since been pushed to later dates under the Digital Omnibus. Each of those dates is a separate event, and each one quietly rewrites the distance between what a product's documentation says and what the law now demands.
State-level rules move on their own clock entirely, with no advance warning built in. California's AI synthetic-performer disclosure law, signed September 16, 2026, is a clean example: the moment it was signed, any documentation that didn't address AI-generated media became out of date, with no grace period for a content team to catch up.
The enforcement side is accelerating too. The ASA's AI-based Active Ad Monitoring system is scaling up through 2026 to proactively identify non-compliance, covering influencer disclosure rules, unfair commercial practices (where the CMA holds direct enforcement power under the DMCCA), and green-claims standards. A regulator adding automated monitoring capacity signals where scrutiny is about to intensify, independent of any single rule it enforces.
Every one of these milestones opens a gap, visible in a product's documentation, between what it currently says and what its users now need to do to stay compliant. That gap is a content brief. It has a subject, an audience, and a deadline already attached to it. Whether anyone notices it in time to act determines the outcome.
Turning a regulatory event into a content brief with real developer intent
A regulatory change creates an immediate, practical question in a developer's head: what changed, does it apply to this stack, and what now has to be done differently? That question gets typed into a search bar before it ever becomes a support ticket. The content opportunity exists at the moment of the regulatory event, not weeks later when someone finally files the ticket.
The shape of the content follows directly from the shape of the event. If a new disclosure requirement lands, like influencer ad-labelling enforcement or the AI chatbot disclosure obligations under the EU AI Act, you need a plain explainer and updated integration documentation showing exactly where the disclosure has to live in the product flow. A tightened enforcement posture, like the ASA applying targeted sanctions for repeated influencer-disclosure breaches, or the CMA using its expanded consumer protection powers under the DMCCA, calls for something more operational: a compliance checklist, or a short post answering the specific question "what does this mean for your integration."
The event supplies its own brief. The regulatory text is the what, the developer workflow it touches is the who, and the implementation step required is the how. Nobody has to invent an angle or stare at a blank page waiting for inspiration. The work is reading the event correctly and writing it down before the moment passes.
Why teams miss these signals and publish nothing instead
Most teams that let this opportunity slip by are slow despite knowing about the regulation. By the time a regulatory update travels from a government portal through a legal review, up to a product manager, and finally down to whoever writes the content, the window when developers are actively searching for an answer has already closed.
A second pattern is misrouting rather than delay. Regulatory updates tend to land in legal or compliance inboxes and get treated purely as internal risk, something to flag and file, and they never cross over to the engineering or developer-relations side of the organization that would actually recognize the content opportunity sitting inside them.
The sharpest failure mode for content teams specifically is calendar lock-in. Teams that plan posts weeks ahead have no open slot for something that happened yesterday. The regulatory change gets mentioned once in a Slack thread, somebody says "we should probably write something about this," and then the thread scrolls away and nothing gets published. The editorial calendar wasn't built to absorb an event with no lead time, so the event just doesn't make it in.
There's a real objection buried in all of this: automated detection can catch a regulatory change the moment it happens, but figuring out who it applies to, what it actually requires, and how serious it is still takes judgment that no scraper can supply. If you publish something built on a misread regulation, that's worse than publishing nothing, because developers will implement whatever they read. The fix is to put the human review step at the interpretation stage, right after detection, asking whether the whole premise is right before a draft exists.
A signal-to-content pipeline for regulatory events
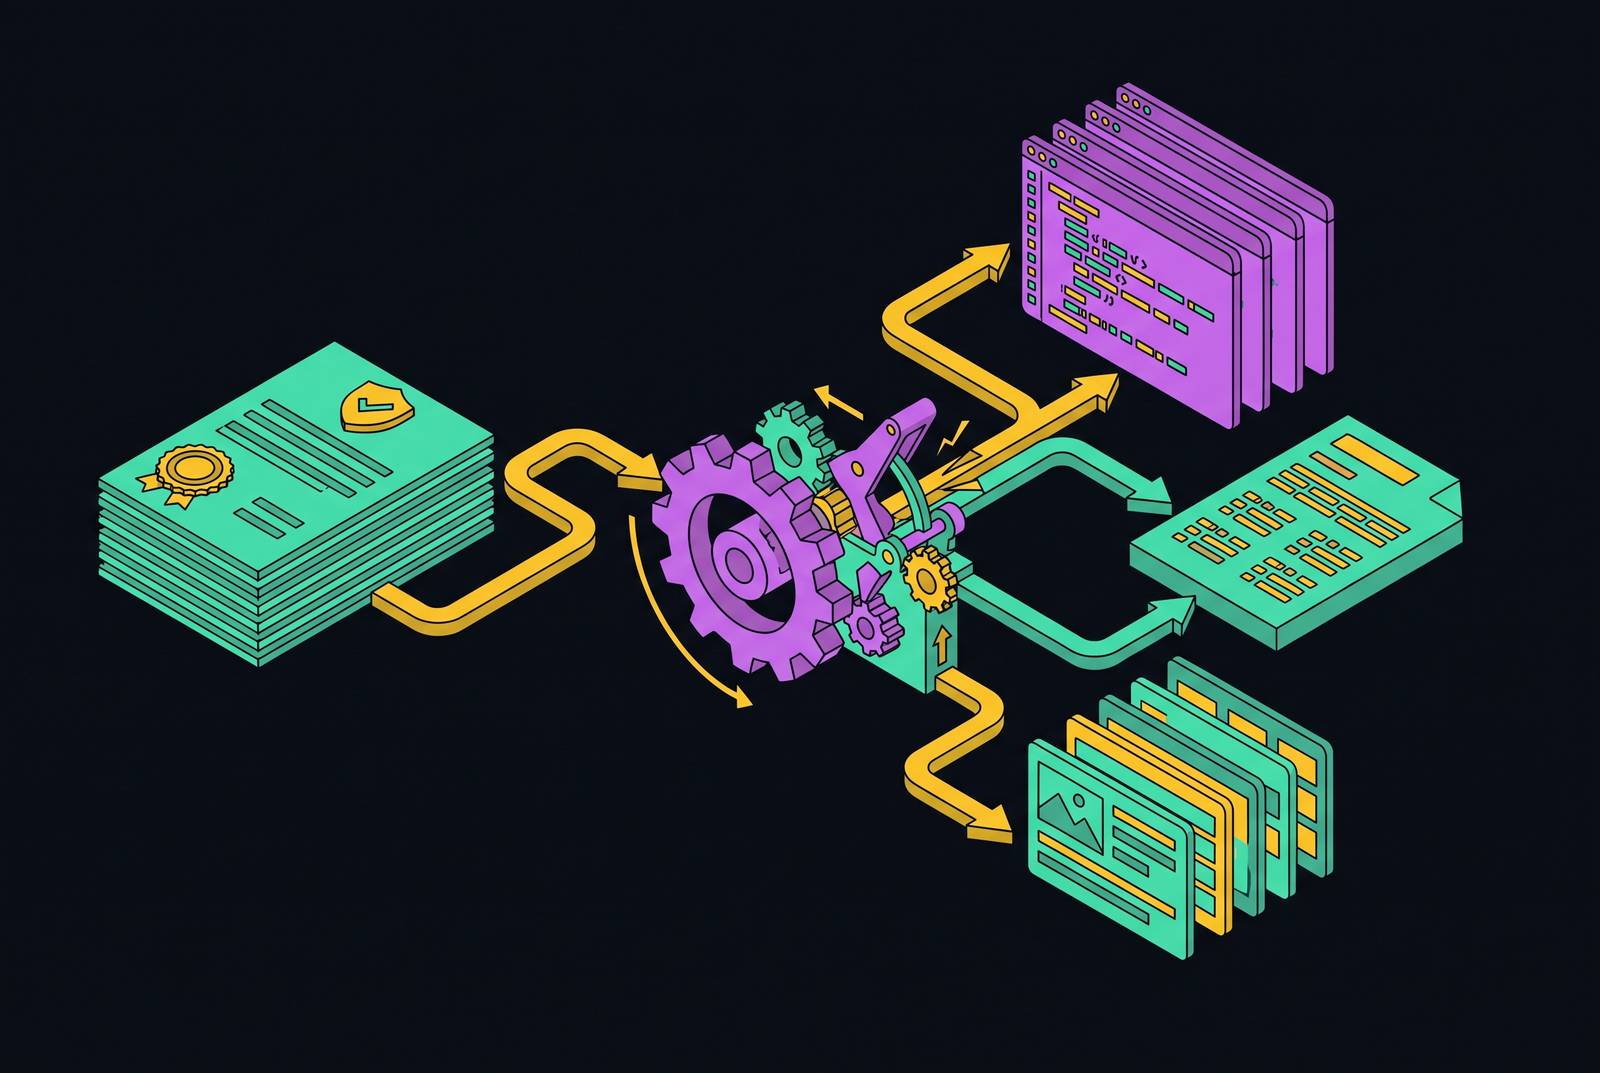
A working pipeline for this problem has three stages: detection, scoring, and drafting. The first two have to happen before anyone writes a single sentence.
Detection means continuous monitoring of official government portals and regulatory body publications, filtered through keyword watchlists tuned to the product's own domain. For a developer-tool company, that watchlist might include terms like AI labeling, data residency, API authentication, consent, and audit logging. Structured scrapers run against these sources can pull out severity indicators, the issuing agency, the publication date, and the source URL, enough information to triage a signal without anyone having to read the full regulatory text first.
Scoring is what keeps that detection useful rather than overwhelming. A regulatory update about tobacco advertising is noise to an API platform. A new AI-provenance labeling requirement is a high-priority signal for that same platform. Testing each incoming update against the product's actual positioning is what protects a small team's time: without that filter, every regulatory update looks like a potential brief, and a lean team drowns trying to evaluate all of them instead of acting on the ones that matter.
Once a signal clears that scoring threshold, drafting can start, and the event itself supplies most of the brief: the regulatory text, the API endpoint or product behavior it touches, and the specific action a developer needs to take. A person still reviews the interpretation and approves the framing, but the draft grows out of a grounded brief instead of a generic prompt typed in from scratch.
Letterseer is built around exactly this pipeline. It monitors regulatory updates as one of six source types it tracks, scores every incoming change against a customer's own positioning before it ever surfaces as a brief, and then produces a finished draft from what clears that bar. In Suggest mode, a person approves the headline before anything goes out. In Autopilot mode, the full pipeline runs without a person in the loop. For a small developer-marketing team, that means a regulatory event that landed overnight can be a published explainer or migration guide by the next morning, without anyone touching an editorial calendar or starting from a blank document.
The changelog as the right format for regulatory-triggered developer content
The changelog is the format developers already trust for this kind of update. It's dated, versioned, tied to a real event, and hard to fake, since a dated record of what changed, week after week, is checkable in a way a blog post about company strategy never is.
A regulatory-triggered changelog entry tends to carry more urgency than a feature-announcement entry sitting next to it. A reader isn't just curious about what's new. They may be blocked on shipping their own deployment until they understand what a compliance requirement means for their integration.
The same underlying content can serve three audiences without three separate writing efforts. A public entry at something like /changelog, written in plain language, dated, and linked to the relevant documentation, serves anyone who lands there directly. A changelog newsletter summarizing the week's regulatory and product changes together reaches the audience that would never think to check /changelog unprompted. And the raw structured notes behind both versions can feed straight into updated API documentation, so the compliance detail doesn't live in only one place.
Linear's changelog, at linear.app/changelog, is a useful model to study here: dated entries, plain language, illustrated where it helps, published on a steady cadence rather than in sporadic bursts. PostHog's "Array" newsletter takes the format a step further by combining the changelog with company context and direct links to the GitHub issues behind each change, adding a layer of transparency through its public issue tracker.
Regulatory events as release-storytelling opportunities for open-source teams
Open-source teams carry an advantage here that no proprietary competitor can copy: a public commit history. A regulatory-triggered code change, a new field, a deprecated endpoint, an updated auth scope, can be traced in full from the original regulatory text, to the merged pull request that implemented it, to the changelog entry, to the published explainer that walks a developer through what to do next.
That traceable chain is the story on its own. Regulation arrived, here's the pull request that implemented the required change, and here's what an integration needs to do differently as a result. The transparency itself is what sets this content apart from a competitor's version of the same announcement.
Docker's Hardened Images arc shows the full version of this chain. Supply-chain security requirements pushed Docker toward building Hardened Images in the first place, the product launched in May 2025, the project was open-sourced in December 2025, and the full backstory was later told on the Changelog podcast in conversation with Docker's CTO, Tushar Jain. That's a complete arc that started with a compliance pressure and ended in organic press coverage.
Most open-source teams leave this on the table. Every commit is already public, but very few teams take the extra step of narrating what any individual commit means for the people using the project. A changelog entry closes that gap between what shipped and what got explained, and if a regulatory-triggered change goes unexplained, it just becomes a support ticket somebody has to answer manually later.
Keeping AI-generated drafts from regulatory signals credible
The skepticism developers have toward AI-written content is earned. Most AI-generated content reads as AI-generated: technically accurate, but flat, generic, and recognizable by a set of tells developer audiences have already learned to spot, from excessive em dashes to filler transitions to vague claims that don't commit to anything specific.
The fix is structural. Content drafted from a specific regulatory event, a named API endpoint, a concrete developer action, and the product's actual positioning starts from specificity instead of having to fake it afterward. A generic AI draft reads badly because it started from an empty prompt and a vague instruction. A draft that starts from a real regulatory text and a real affected endpoint doesn't have that problem to begin with, because the brief itself is already specific before a single sentence gets written.
None of this removes the need for quality control. Publishing a misread or generic regulatory explainer does real damage: it hands developers instructions they'll implement, and it teaches the audience to stop trusting the changelog going forward. The discipline that makes this work isn't reviewing drafts faster. You do the real work at the scoring and grounding stage, before drafting even starts, so speed never comes at the expense of getting the regulation right.
Building the habit: treating regulatory monitoring the same way teams treat merged pull requests
Engineering teams already run on a trigger model: a merged pull request fires a pipeline automatically, tests run, a build gets produced, documentation updates, a deployment happens, all without anyone having to remember to kick it off by hand. A regulatory event that clears the scoring threshold deserves the same treatment. It should fire a content pipeline directly, instead of landing in a Slack channel and waiting for someone to remember it.
Many developer-marketing teams already run an integrated launch checklist for product features: engineering declares something feature-complete, marketing drafts in parallel, developer relations runs a community preview, and a blog post goes live on launch day. That same workflow maps onto regulatory events almost without modification. Swap "engineering declares feature-complete" for "regulatory event clears the scoring threshold": the rest of the process runs the same way.
Smaller teams don't need the full version of that workflow to benefit from the habit. A weekly batch works just as well: filter the week's regulatory signals that cleared the scoring threshold, let a drafting tool produce the plain-language rewrite from the structured event data, then have the founder or an engineer sit down once, review the week's drafts together, fix any misread interpretations, and publish. When a regulatory change also happens to trigger a code commit, a new field, a deprecated endpoint, an updated auth scope, it enters that same pipeline exactly like any other merged pull request would.
The distribution argument strengthens the case further. As broadcast social platforms become less reliable for reaching developers, an owned channel like a public changelog URL and its companion newsletter only grow more valuable, not less. A regulatory-triggered explainer published there and sent to subscribers reaches the developers who actually need it, on a channel they already check and trust, without depending on an algorithm to decide who sees it.
Letterseer fits into this same shift as one option built for teams that haven't yet built their own monitoring and scoring infrastructure: it watches regulatory updates alongside merged pull requests, scores each signal against the product's own positioning, and turns what clears that bar into finished content. The underlying goal is the same one engineering teams already take for granted with continuous deployment: ship when the signal is ready.