Content Workflows for One-Person Marketing Teams at Dev Tool Startups
Solo marketers win by extracting stories from engineering work, not inventing them from scratch.
If a one-person marketing team at a dev tool startup races a staffed content operation, it loses, and it loses before the first post even publishes. The devtools market grows so fast that a five-person content team at a well-funded competitor can outpublish a solo marketer on raw count, week after week, with no ceiling in sight. Volume is not a fight a single person wins, so the job has to be redefined around something other than output speed. Developers also don't arrive the way a volume strategy assumes: they research independently through GitHub, Reddit, Hacker News, newsletters, and AI assistants, and by the time they reach a vendor they are already informed. Developer marketing practice in 2026 confirms this: the discovery journey runs through docs, community threads, and AI answers long before any sales conversation starts. A campaign built to generate broad awareness rarely lands at a moment when it can change a developer's mind.
The audience a solo marketer addresses has also gotten more complicated. Trust compounds the difficulty. A solo marketer cannot out-produce a staffed team, and trying to is a waste of the one resource that can't be replenished: time. The alternative is not to produce less content of the same kind. Instead, you stop inventing content at all, because the material a one-person team needs is already there, written daily, inside the engineering team's own output.
What engineering's output already contains that marketing hasn't claimed
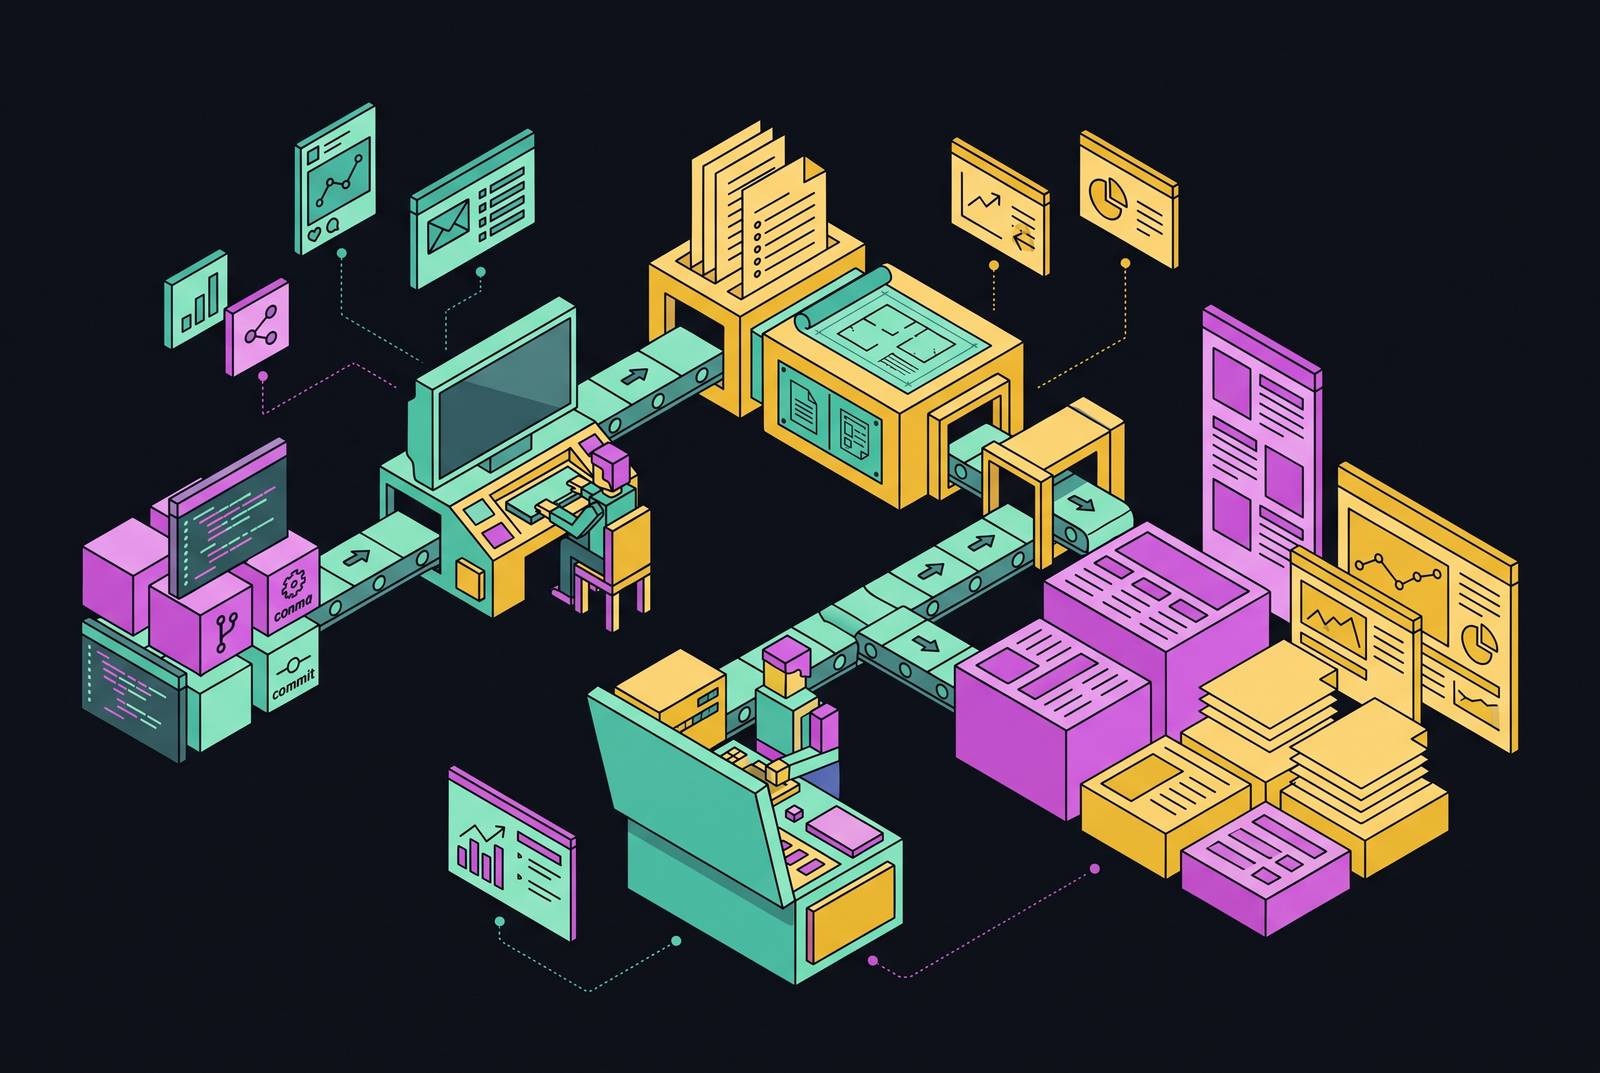
Picture the commit log of any active dev tool repository on a Tuesday afternoon. Pull requests are merging, a release gets tagged, an OpenAPI spec picks up a new endpoint, a roadmap item gets closed out. None of that is content yet, but all of it is a story waiting for someone to tell it. Commits, pull requests, releases, API spec changes, and roadmap completions form a continuous stream of audience-facing material that goes unpublished, and the reason isn't that it lacks value. It goes unclaimed because no one on the team has built a workflow that turns engineering signal into marketing output.
At most dev tool companies, the founders and engineers are already the first people writing about the product, in commit messages, PR descriptions, and release notes. That fact reframes what a solo marketer's job actually is: extraction and translation, not invention. You can sort the raw material into three distinct layers. Product signals are the "what shipped" layer, merged PRs, tagged releases, closed roadmap items. Market signals are the "what changed in the environment the product operates in" layer, including regulatory updates, industry-standard shifts, and competitor spec changes, and most solo marketers ignore this layer entirely because it sits outside their own repo.
The specification layer carries weight that it didn't carry a few years ago. A well-maintained, publicly accessible OpenAPI spec is a direct adoption driver for that reason, not a courtesy an engineering team extends to marketing. The discipline that follows from all of this is simple to state: treat the change itself as the brief. Content grounded in a real commit or a real spec diff is sharper than content built from a prompt alone, because the event supplies specificity that a generic instruction cannot manufacture.
The changelog as the structural center of a solo marketer's content program
If engineering's output is the raw material, the changelog is where it gets built into something an audience actually reads. A public changelog is the highest-leverage asset a one-person dev tool marketing team can maintain, because it produces SEO traffic, drives feature adoption, and builds prospect trust, all without requiring the marketer to invent anything. The work is curation and translation of commits that already exist.
A useful way to think about the changelog is as a three-layer structure, derived from the same feat: and fix: commits running through the repo. The first layer is the technical CHANGELOG.md file that lives in the repo itself, following the Keep a Changelog format with its Added, Changed, Deprecated, Removed, Fixed, and Security categories. Its audience is narrow and specific: developers integrating with the API, contributors to the codebase, and technical evaluators doing diligence before a purchase decision. It updates with every release, not on an editorial schedule.
Three companies illustrate different points on this spectrum, and Resend is the one that matters most for a team of one. That is the proof point a solo marketer needs. You don't need a design team or a visual production pipeline to run a meaningful changelog. It requires discipline about publishing what actually shipped, in plain language, on a consistent schedule.
The conversion mechanics behind this drive real results. The SEO mechanics compound that effect in three ways. A changelog entry titled "Stripe webhook retry support added" ranks for a long-tail, buyer-intent query that a dedicated blog post built around a broader topic would never target. None of that requires a new piece of writing invented from nothing. It requires a system that reliably turns shipped work into published entries.
Automating the commit-to-changelog pipeline without an editorial calendar
A cadence of 2-5 changelog entries per week is only sustainable for a solo marketer if the pipeline from commit to draft runs on automation. Manual curation at that frequency consumes the entire content budget a single person has, leaving nothing for anything else the role needs to cover.
The source layer of that pipeline starts with filtering the repo's feat: and fix: commits on a weekly cadence. Conventional commit messages, along with their bodies, are the raw material the pipeline reads. Scoring changes against the product's own positioning is how a solo marketer protects limited time, because not every commit is a story, and a tool that filters out the noise before drafting begins saves the only resource that can't be recovered later.
If a team has less technical capacity for building a custom pipeline, it can start with a Zapier automation that triggers an AI draft the moment a GitHub release gets tagged. It is not the most sophisticated option, but it closes the gap between shipping and publishing without custom engineering work.
GitHub itself can serve as more than a code repository in this setup. If prompts, ICP profiles, tone-of-voice documents, and workflow exports sit in a version-controlled repository, tools that read that context directly can reuse it without being re-explained in every session. That is the same pattern engineering already uses for code, applied to content operations: voice guidelines and prompt templates function as artifacts with a commit history, not documents that drift unnoticed over months.
The pipeline matures into two operating modes as it develops. In suggest mode, the pipeline drafts a post and the marketer approves the headline before it publishes, so it fits a brand voice still being established or a content type the team hasn't run before. In autopilot mode, the pipeline runs from signal straight to published post without intervention, which fits well-defined, stable content types like changelog entries, where the format and the voice have already been proven out.
API and spec monitoring as a second publishing trigger the solo marketer controls
Every change in engineering output is a signal worth automating around. Every change to a public API or OpenAPI spec is its own content event: an endpoint added, a parameter deprecated, a new schema introduced. Each one supports a legitimate "what changed and why" post, a migration guide, or a tutorial walking through the new capability. Solo marketers overlook this layer entirely, and it effectively doubles the available publishing surface without asking the marketer to invent a single new idea.
The mechanism is straightforward: a solo marketer can hook into the same alert stream that engineering already uses for API monitoring and treat every alert as a publishing trigger. The technical diff is the brief. There is no gap between the event happening and the story being ready to write, because the spec change is already documented by the time the alert fires.
How software gets built now has made this more urgent. A well-maintained, publicly accessible spec, with precise endpoint descriptions and complete schema definitions, makes the API accurately representable to AI coding assistants and agentic workflows. That makes spec quality a marketing output in its own right, not just an engineering artifact, because as AI-assisted development becomes the default way software gets built, a clean spec directly drives adoption. Developer marketing practice in 2026 has already registered this shift: AI assistants now answer a query like "best error tracking for a Node API" before a developer ever opens a search results page, and being represented accurately in that answer depends on having content and specs the assistant can actually cite.
Documentation platforms have started building toward this reality directly. ReadMe supports custom pages, getting-started guides, changelogs, and branded themes, and with the October 2025 launch of Agent Owlbert AI, the platform added an AI writing assistant, Agent Owlbert, alongside AI-powered style enforcement through its Linter. ReadMe also surfaces page-level doc metrics, including page views, page quality, and search terms, on each documentation page, along with API adoption analytics across endpoints. That combination gives a solo marketer visibility into exactly where developers stall in the docs, turning prioritization into a measurement exercise grounded in data.
If regulatory shifts and industry-standard changes hit a product's market, they deserve the same treatment as the product's own releases. A solo marketer who monitors that environment can publish "what this means for your integration" content the moment a relevant change lands, something a competitor watching only their own repo has no way to produce on the same timeline.
Writing AI-generated changelog and technical content that developers will not dismiss
The obvious criticism of any automated content pipeline is that it produces generic output, and for a developer audience that reflexively checks claims against docs and GitHub, generic output is worse than no output. The criticism has a specific cause, though, and it's fixable: AI-generated content sounds generic because it receives generic instructions. Voice is a set of rules specific enough to argue with, since an instruction like "friendly and professional" describes roughly half the internet.
The structural fix starts with a vocabulary reference built around three columns: preferred terms the brand uses consistently, banned phrases that signal generic or off-brand writing, and a shorter "use sparingly" list for terms that are acceptable but shouldn't dominate. The Flip-Side Method adds a third layer of control: define every brand voice trait by pairing it with the nearby thing it must never become, so "witty, never snarky" forces a model to hold a boundary instead of drifting toward the easier, flatter approximation.
None of that matters if the content itself can't survive scrutiny. Developer audiences verify claims in docs and on GitHub as a matter of habit, so content that cannot be reproduced or checked is a liability. Every generated post needs specific, verifiable facts drawn from the actual commit or spec change that triggered it, not adjectives about how good the product is. This is where the signal-first workflow earns its advantage structurally: content grounded in a real commit or spec change carries a level of specificity that only the event itself can supply, with the model's job limited to translation. Volume without that quality bar is a liability, because a published post that a senior engineer has to correct in public does more damage than the post not existing.
There is a point at which outsourcing becomes the more rational choice. Draft.dev operates a network of more than 300 vetted engineer-writers, with plans starting at approximately $9,000 a month on a three-month minimum, and that figure is a useful benchmark for what an in-house, signal-first workflow has to beat before the investment in automation actually pays off.
Measuring what works without a five-person analytics team
A signal-first workflow is only defensible if a solo marketer can show it is working, and the metrics that matter for a dev tool audience look nothing like the metrics a traditional content program tracks. Measurement here has to center on technical engagement: API key creation, first successful call, documentation page exits, GitHub interactions. Those are the signals that predict conversion for a developer audience, where pageviews and click-through rates tell a marketer almost nothing about whether a reader became a user.
Amplitude and a second tool are worth evaluating in this specific context. Amplitude suits cross-functional teams that need intuitive, self-service reporting without requiring SQL expertise from whoever is reading the dashboard, which matters when the buyer persona, an engineering manager or a VP, needs to read results without pulling in a data analyst.
Two warning signs show when the tool stack itself has become the bottleneck, not the solution. At that point, consolidating toward a single platform that can research, plan, create, publish, and optimize across channels is the more defensible move, and it shifts the marketer's role from prompt engineer to editorial director overseeing a system.
One measurement category didn't exist two years ago and now needs its own tracking: AI discovery. Developers increasingly ask AI assistants direct questions, like "best error tracking for a Node API," and receive answers assembled from pages the assistant can cite. A solo marketer needs to know whether the brand shows up in those answers, not only where it ranks on a traditional search results page. Marketing, treated this way, becomes an engineering discipline in its own right: instrumented, measured, and adjusted on evidence. The signal-first workflow isn't finished once the pipeline publishes. It closes the loop only when the marketer can see which published signals actually drove activation, and feed that evidence back into the scoring step that decides what gets published next.